01 — Project
Multimodal Knowledge Engine
Cited answers over documents, images & voice
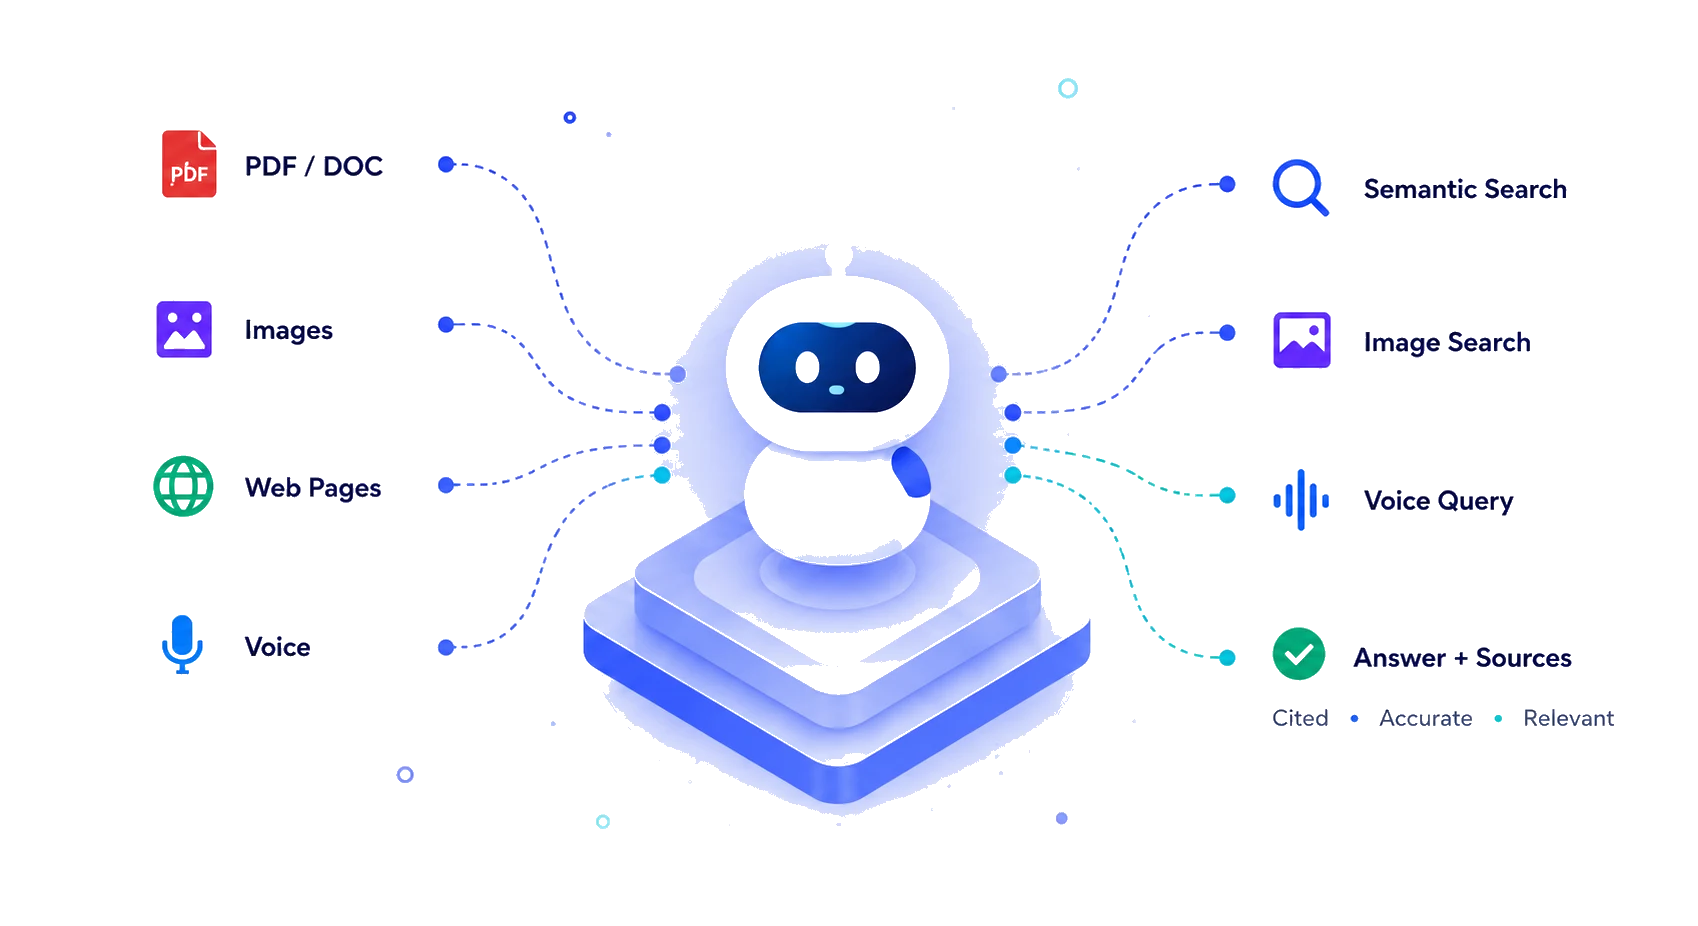
Indexes docs, images, and web content — then answers with cited sources over REST and voice.
1k
Documents Indexed
500ms
Avg. Retrieval Time
95%+
Answer Accuracy
Multi-modal
Text · Images · Voice · Web
Enterprise Ready
Secure · Scalable · Reliable
02 — Retrieval Pipeline
1. Ingestion
Upload docs or scrape websites
2. Extraction
Extract text, images and metadata
3. Chunking
Smart chunking (250–900 tokens)
4. Embedding
Multi-vector embeddings
5. Vector DB
Index in Qdrant collections
6. Hybrid Search
Semantic + Keyword + Filters
7. Reranking
Cross-Encoder reranking
8. LLM Generation
DeepSeek generates grounded answers
9. Answer
Answer with sources & score
1. Ingestion
Upload docs or scrape websites
2. Extraction
Extract text, images and metadata
3. Chunking
Smart chunking (250–900 tokens)
4. Embedding
Multi-vector embeddings
5. Vector DB
Index in Qdrant collections
6. Hybrid Search
Semantic + Keyword + Filters
7. Reranking
Cross-Encoder reranking
8. LLM Generation
DeepSeek generates grounded answers
9. Answer
Answer with sources & score
03 — Why RAG?
The Problem
LLMs hallucinate, can't access private documents and struggle with images and unstructured data.
The Solution
Hybrid retrieval with multi-vectors, reranking, OCR and multimodal understanding.
The Outcome
Accurate, source-cited answers with high precision and low latency.
04 — Key Metrics
1k
Documents Indexed
20k+
Embeddings Generated
480ms
Avg. Retrieval Latency
95%+
Answer Accuracy
8
Top-K Chunks Used
512
Chunk Size Tokens
Retrieval Latency (ms)
480ms
+18%Answer Accuracy (%)
95.2%
+6.4%Queries (30d)
18,642
+12.7%Documents Indexed
1k
+15.3%04 — Architecture
System architecture
From multimodal ingestion through hybrid retrieval to grounded LLM answers — with tenant isolation, caching, and dual delivery channels.
Data Sources
Ingestion
Storage (S3)
Processing
Embedding
Query Router & Orchestrator
Qdrant Vector DB
Cache · Session
Retrieval
Auth
LLM
Delivery
Horizontal diagram is optimized for desktop. On mobile, flow is: Sources → Ingest/S3 → Process → Embed → Qdrant → Retrieve → LLM → REST / Voice.
06 — Supported Modalities
PDF Documents
Word Documents
Excel Sheets
Images & Diagrams
Scanned Documents
Web Pages (HTML)
Voice Queries
CSV Files
Voice-to-Text Responses
Email Files
Text Documents
PPT / Slides
07 — Platform Features
Semantic Search
Hybrid Retrieval
Cross-Encoder Reranking
OCR & Text Extraction
Image Search (CLIP)
Voice Interaction
Source Citations
Metadata Filtering
Streaming Responses
REST API First
Rate Limiting & Security
Multi-Tenant Isolation
Interested in how we built it?
Indexes docs, images, and web content — then answers with cited sources over REST and voice.